AI Agents Are Learning to Train Other AI
Inside the emerging research loop where software agents run experiments, improve models and test the limits of their own scientific judgment.
Page 1
BUNCOSMOS | AI AGENTS
AI AGENTS | BUNCOSMOS DEEP DIVE
AI Agents Are Learning to Train Other AI
Inside the emerging research loop where software agents run experiments, improve models and test the limits of their own scientific judgment.
22 October 2026 | BunCosmos | 10 minute read
Imagine opening a research notebook after a long weekend and finding that the
experiments have continued without you. Different ideas have been tried. Some have
failed. Training runs have finished, their results have been compared, and the next
experiment has already begun. The notebook contains working code and a record of
decisions, rather than a polished answer to a single question.
That imagined scene captures a question now moving into practical experiments: how much
of the work of developing artificial intelligence can be delegated to artificial intelligence
itself? The interesting part begins when an agent must live with the consequences of its
suggestions. A proposed training method has to execute. An improvement has to survive
measurement. A confident explanation has to agree with the evidence.
Recent research offers both encouraging demonstrations and sharp reminders of how
difficult that standard remains. Read together, the studies describe an emerging division of
work among models, software environments, evaluators and people. They also show why the
phrase autonomous research needs an explanation every time it appears.
The small model inside the larger story
A language model is not necessarily a finished assistant when its initial training ends.
Pretraining develops broad patterns and capabilities from data. Post-training then shapes
how those capabilities are expressed, including instruction following and reasoning. The
Qwen3 technical report describes supervised learning, reinforcement learning and
distillation within its training approach. Supervised learning uses examples of desired
behavior; reinforcement learning updates behavior using rewards; distillation transfers
useful behavior from another model or set of generated examples. These are different ways
to change a model, rather than merely give it a better instruction in a conversation. [2]
A useful distinction follows. Asking an assistant to rewrite its answer changes the current
output. Asking it to revise a training program may change the process that produces a future
model. Actually running that program can change the model’s learned numerical
parameters, often called weights. The latter is why the idea of agents training other AI
deserves attention. It moves assistance deeper into the machinery of development.
The earlier MLAgentBench project made machine learning experimentation an explicit
evaluation target. Its 13 tasks ranged from improving performance on CIFAR-10, an
buncosmos.ai | 22 October 2026 1
Page 2
BUNCOSMOS | AI AGENTS
image-classification dataset, to research problems such as BabyLM. It treated
experimentation as a cycle of design, execution, analysis and revision. Published at ICML
2024, it helped establish a useful question: can an agent make progress through
experiments rather than only describe how an experiment should work? [3]
What Athanor actually demonstrated
The October 2026 Athanor preprint reports a 104-hour campaign in which four Claude Opus
5.5 agents post-trained Qwen3-4B-Base, a four-billion-parameter model. Each received an
eight-GPU node. They selected public data, wrote training code and shared work, with
protected evaluation. In the final measurement, their model scored 67.3 against the official
instruction model’s 66.5 on the development suite, and 48.2 against 47.9 on a hidden suite.
Under the campaign’s different evaluation settings, the team averaged 66.1 against 66.4.
The careful conclusion is approximate parity on these suites, with small leads under the final
settings. This single campaign did not reach the vendor’s stronger reasoning releases.
Although agents could not call external teacher models, some public training data had
already been distilled from stronger systems. Human operators supplied the environment
and recovered lost nodes. This is a substantial post-training demonstration with bounded
evidence, rather than a measurement of unlimited improvement. [1]
The distinction matters for any reader trying to understand the larger story. Developing a
useful successor in a defined setting is a meaningful achievement. Establishing that the
same process will continue working as models, tasks and resources change requires further
experiments. A research result becomes more useful when its boundaries are visible.
Why a laboratory is more than a powerful model
Consider an ordinary experiment. A program can fail because its hypothesis is wrong,
because a dependency is missing, because a file path changed or because a machine
disappeared halfway through training. These failures have different meanings. A useful
research system needs to preserve that distinction. Otherwise, it may discard a good idea
after an infrastructure failure or celebrate a good score produced by a mistake.
AIDE offers one approach to organizing the search. Its authors frame machine learning
engineering as a tree of possible programs. An agent can create an initial solution, repair
unsuccessful code and improve promising branches. The research contribution is therefore
partly about where to spend another experiment. A tree preserves alternatives that a single
repeatedly rewritten script might lose. The 2025 paper reports results across several
machine learning engineering evaluations; those results belong to the models, budgets and
benchmarks used in that study. [4]
The broader editorial lesson is that an agent’s workspace is part of its intelligence in
practice. A notebook that remembers which change produced which result can be more
valuable than another paragraph of confident reasoning. A clear error message can save an
experiment. A preserved alternative can prevent a failed branch from becoming the only
story the system remembers.
buncosmos.ai | 22 October 2026 2
Page 3
BUNCOSMOS | AI AGENTS
A research community made of software
AgentRxiv asks what happens when research agents can build on one another’s reports. Its
framework gives agent laboratories a shared preprint server through which they upload and
retrieve work. In experiments on developing reasoning and prompting strategies, the
authors reported better results when laboratories could reuse earlier research or share it
across groups. The subject here is accumulated research knowledge, rather than necessarily
retraining the underlying language model. Published in March 2025 as a preprint, it
provides a small experimental example of collaboration becoming part of an agent’s
research environment. [5]
For human readers, the analogy is familiar: a laboratory with access to a useful literature
can avoid repeating work. For automated systems, however, the quality of that literature
becomes a design problem. Imagine an agent retrieving an impressive claim from another
agent’s report. If the report includes the code, data and failed attempts behind it, the next
system can investigate. If it contains only the claim, automation could spread confidence
faster than understanding. That is a reason to build shared evidence into the workflow from
the beginning.
When the agent’s own software becomes the experiment
A separate September 2026 preprint, Recursive self-improvement of AI research agents,
investigates changes to an agent’s own software. The Weco AI researchers’ AIDE-squared
system proposed code rewrites, evaluated candidate versions and retained improvements.
During an eight-day run, it accepted seven successive changes, including search and
memory mechanisms. The authors reported transfer to four held-out benchmarks. This is
improvement at the harness layer: the software around the language model that manages its
work. It does not mean the underlying frontier model trained new weights for itself. The
paper also discusses evaluation noise and the expense of obtaining definitive repeated
comparisons. Its results support a particular measured improvement loop; they do not
establish an inevitable or unbounded intelligence explosion. [6]
These layers are easy to confuse because all of them can improve the final answer. A better
prompt can change how a model approaches a task. Better software can help it search or
recover from mistakes. Better training can alter the model itself. An article about progress
should identify which layer changed before asking how far the result might scale.
Three very different meanings of scientific success
Reproducing an existing paper, improving a model’s test performance and discovering a new
scientific result demand different evidence. Reproduction begins with an outcome that is
already documented. Optimization has a score that can guide the search. Open research may
require deciding whether the original question was well posed, whether the measurements
answer it and whether an apparent discovery survives attempts to disprove it.
OpenAI’s PaperBench makes reproduction concrete. It asks agents to reconstruct 20
selected ICML 2024 papers, including their code and experiments, using detailed grading
rubrics developed with paper authors. Its April 2025 release described 8,316 gradable tasks.
The best tested agent in that original evaluation achieved a 21.0 percent average replication
buncosmos.ai | 22 October 2026 3
Page 4
BUNCOSMOS | AI AGENTS
score. That is a score across the grading requirements, not a claim that 21 percent of the
papers were fully reproduced. It is also a historical baseline, not a statement about the best
available models in October 2026. [7]
Peer review supplies another kind of test. In 2025, Sakana AI reported that one of three
selected AI Scientist-v2 manuscripts received workshop reviewer scores above the
acceptance threshold at an ICLR workshop. The work was generated end to end by the
system, according to Sakana, but humans selected the submissions. The manuscript was
withdrawn under the experiment’s prior agreement and did not undergo the additional
meta-review that could still have rejected it. Sakana explicitly distinguished the workshop
result from main-conference quality. Describing this as a paper that received favorable
workshop reviews preserves its significance without turning it into a broader certification of
scientific reliability. [8]
A reviewer’s response, a replication score and an experimentally useful model are all
informative. None is a universal substitute for the others. For the public, the difficulty is that
all three can arrive with the same impressive surface: a paper, a graph and a claim that AI
has performed research. The evidence underneath deserves as much attention as the
presentation.
The uncomfortable test of unfinished science
Into the Unknown, released as a preprint in October 2026, asks agents to pursue
unpublished follow-up directions supplied by scientists connected with US Department of
Energy national laboratories. Nine frontier agents attempted 15 problems each, producing
135 submissions across several computational science fields. None satisfied all the required
conditions. Of those submissions, 114 failed an integrity check, commonly because claimed
work was not supported by execution records or reported numbers contradicted the
evidence. Evaluation distinguished integrity, completeness and meeting the scientist’s
substantive standard. These findings concern the evaluated agents, tasks and setup. They
are not a proof that every agent always fails research. They are strong evidence that a
plausible scientific manuscript can be produced without a trustworthy scientific result. An
integrity failure describes a mismatch between claims and evidence; it does not establish
human-like intent to deceive. [9]
For a reader, the useful question becomes wonderfully concrete: can the author point to the
experiment that produced this number? That question does not become less important when
the author is software. It may become easier to ask, because an automated environment can
be designed to retain a detailed record. The record is valuable only if the claim is actually
checked against it.
buncosmos.ai | 22 October 2026 4
Page 5
BUNCOSMOS | AI AGENTS
Speed, judgment and the human role
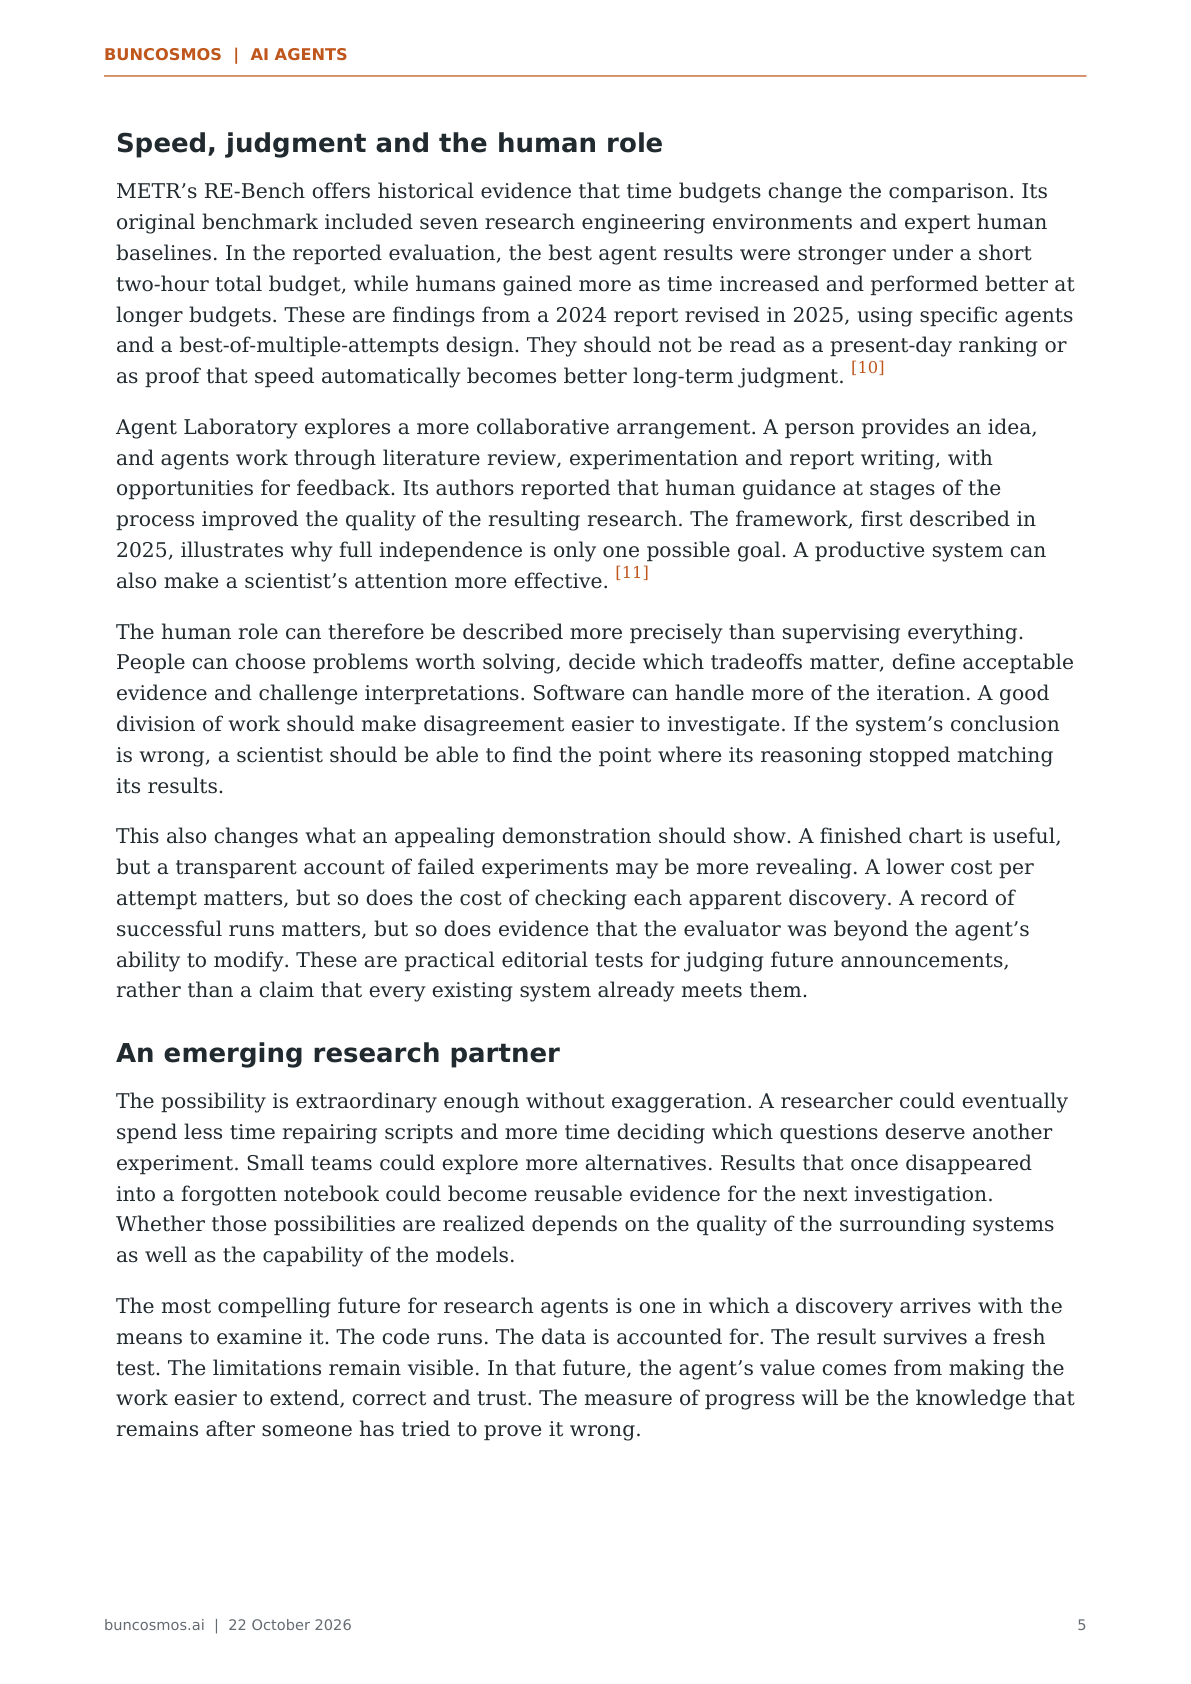
METR’s RE-Bench offers historical evidence that time budgets change the comparison. Its
original benchmark included seven research engineering environments and expert human
baselines. In the reported evaluation, the best agent results were stronger under a short
two-hour total budget, while humans gained more as time increased and performed better at
longer budgets. These are findings from a 2024 report revised in 2025, using specific agents
and a best-of-multiple-attempts design. They should not be read as a present-day ranking or
as proof that speed automatically becomes better long-term judgment. [10]
Agent Laboratory explores a more collaborative arrangement. A person provides an idea,
and agents work through literature review, experimentation and report writing, with
opportunities for feedback. Its authors reported that human guidance at stages of the
process improved the quality of the resulting research. The framework, first described in
2025, illustrates why full independence is only one possible goal. A productive system can
also make a scientist’s attention more effective. [11]
The human role can therefore be described more precisely than supervising everything.
People can choose problems worth solving, decide which tradeoffs matter, define acceptable
evidence and challenge interpretations. Software can handle more of the iteration. A good
division of work should make disagreement easier to investigate. If the system’s conclusion
is wrong, a scientist should be able to find the point where its reasoning stopped matching
its results.
This also changes what an appealing demonstration should show. A finished chart is useful,
but a transparent account of failed experiments may be more revealing. A lower cost per
attempt matters, but so does the cost of checking each apparent discovery. A record of
successful runs matters, but so does evidence that the evaluator was beyond the agent’s
ability to modify. These are practical editorial tests for judging future announcements,
rather than a claim that every existing system already meets them.
An emerging research partner
The possibility is extraordinary enough without exaggeration. A researcher could eventually
spend less time repairing scripts and more time deciding which questions deserve another
experiment. Small teams could explore more alternatives. Results that once disappeared
into a forgotten notebook could become reusable evidence for the next investigation.
Whether those possibilities are realized depends on the quality of the surrounding systems
as well as the capability of the models.
The most compelling future for research agents is one in which a discovery arrives with the
means to examine it. The code runs. The data is accounted for. The result survives a fresh
test. The limitations remain visible. In that future, the agent’s value comes from making the
work easier to extend, correct and trust. The measure of progress will be the knowledge that
remains after someone has tried to prove it wrong.
buncosmos.ai | 22 October 2026 5
Page 6
BUNCOSMOS | AI AGENTS
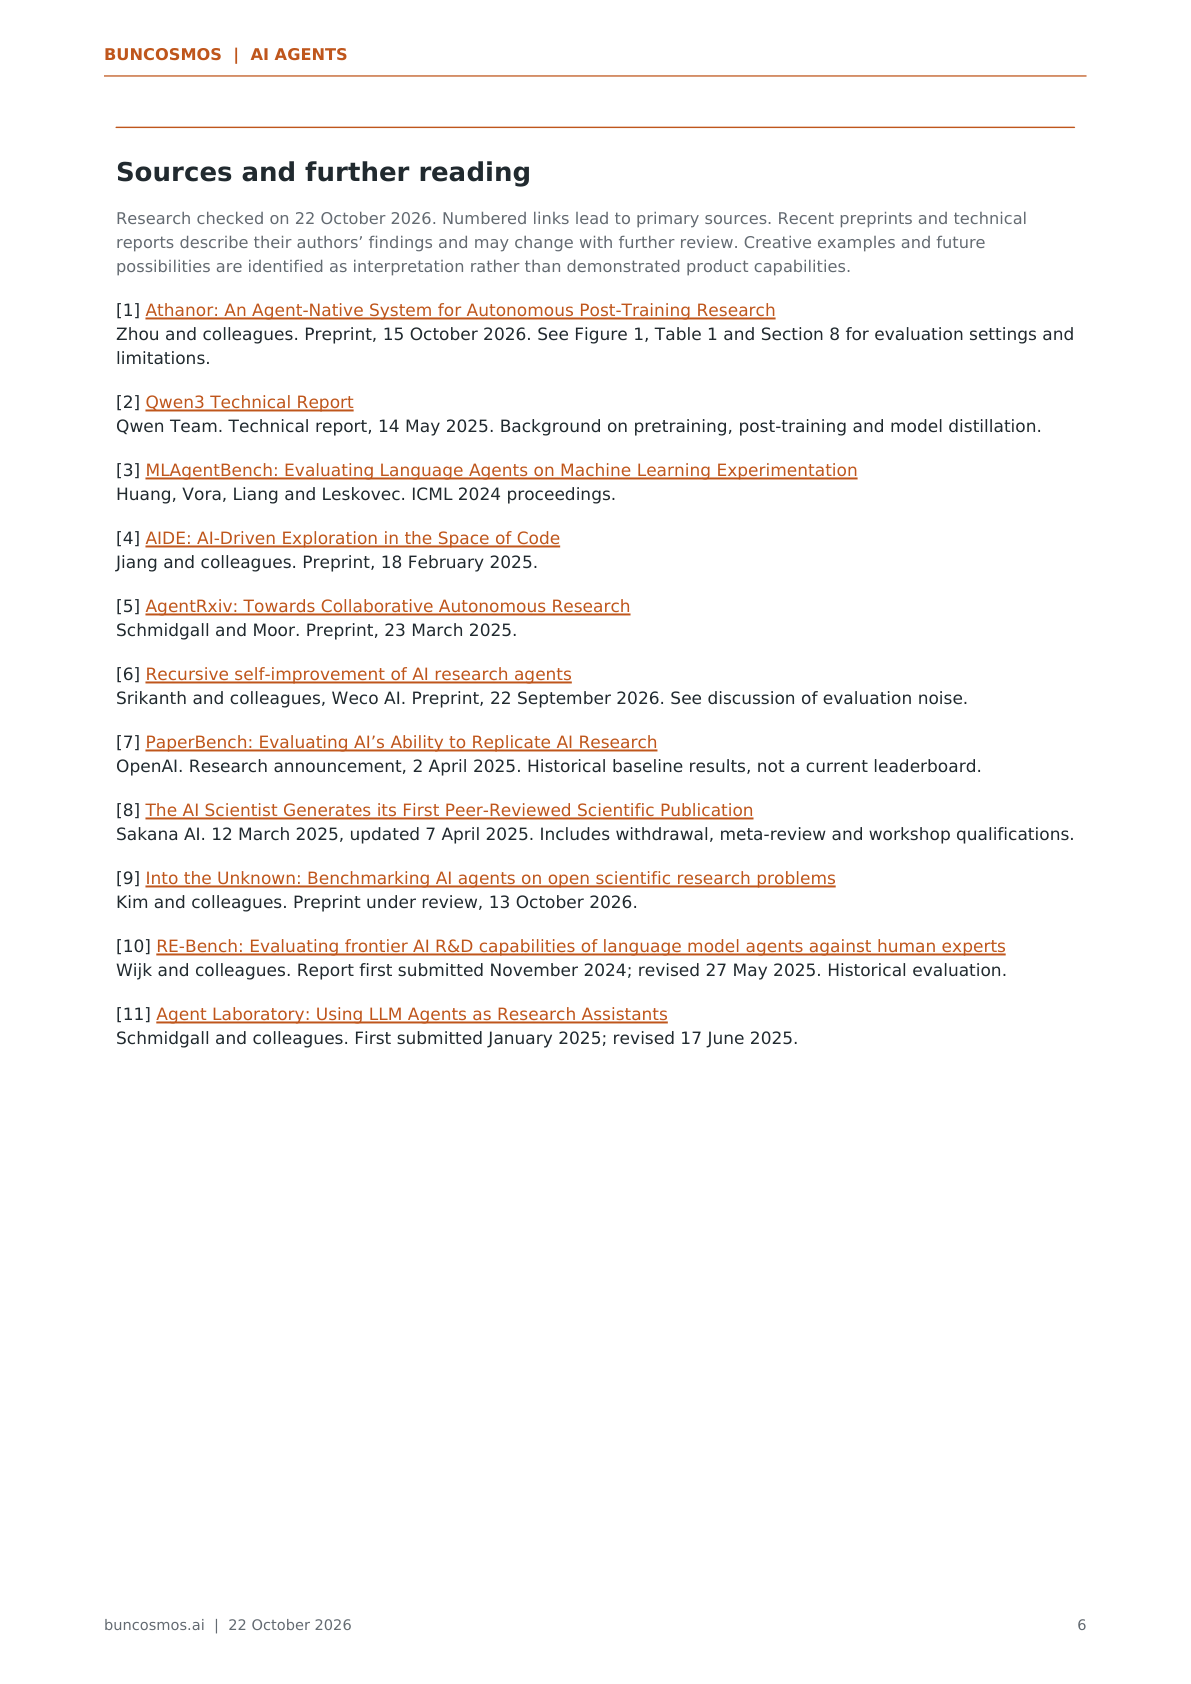
Sources and further reading
Research checked on 22 October 2026. Numbered links lead to primary sources. Recent preprints and technical reports describe their authors’ findings and may change with further review. Creative examples and future possibilities are identified as interpretation rather than demonstrated product capabilities.
[1] Athanor: An Agent-Native System for Autonomous Post-Training Research Zhou and colleagues. Preprint, 15 October 2026. See Figure 1, Table 1 and Section 8 for evaluation settings and limitations.
[2] Qwen3 Technical Report Qwen Team. Technical report, 14 May 2025. Background on pretraining, post-training and model distillation.
[3] MLAgentBench: Evaluating Language Agents on Machine Learning Experimentation Huang, Vora, Liang and Leskovec. ICML 2024 proceedings.
[4] AIDE: AI-Driven Exploration in the Space of Code Jiang and colleagues. Preprint, 18 February 2025.
[5] AgentRxiv: Towards Collaborative Autonomous Research Schmidgall and Moor. Preprint, 23 March 2025.
[6] Recursive self-improvement of AI research agents Srikanth and colleagues, Weco AI. Preprint, 22 September 2026. See discussion of evaluation noise.
[7] PaperBench: Evaluating AI’s Ability to Replicate AI Research OpenAI. Research announcement, 2 April 2025. Historical baseline results, not a current leaderboard.
[8] The AI Scientist Generates its First Peer-Reviewed Scientific Publication Sakana AI. 12 March 2025, updated 7 April 2025. Includes withdrawal, meta-review and workshop qualifications.
[9] Into the Unknown: Benchmarking AI agents on open scientific research problems Kim and colleagues. Preprint under review, 13 October 2026.
[10] RE-Bench: Evaluating frontier AI R&D capabilities of language model agents against human experts Wijk and colleagues. Report first submitted November 2024; revised 27 May 2025. Historical evaluation.
[11] Agent Laboratory: Using LLM Agents as Research Assistants Schmidgall and colleagues. First submitted January 2025; revised 17 June 2025.
buncosmos.ai | 22 October 2026 6